AI Security Architecture: A Practical Enterprise Framework — Part 1
Enterprise AI security depends less on whether a model behaves perfectly and more on whether the surrounding architecture makes trust explicit, limits authority and contains unexpected behaviour.
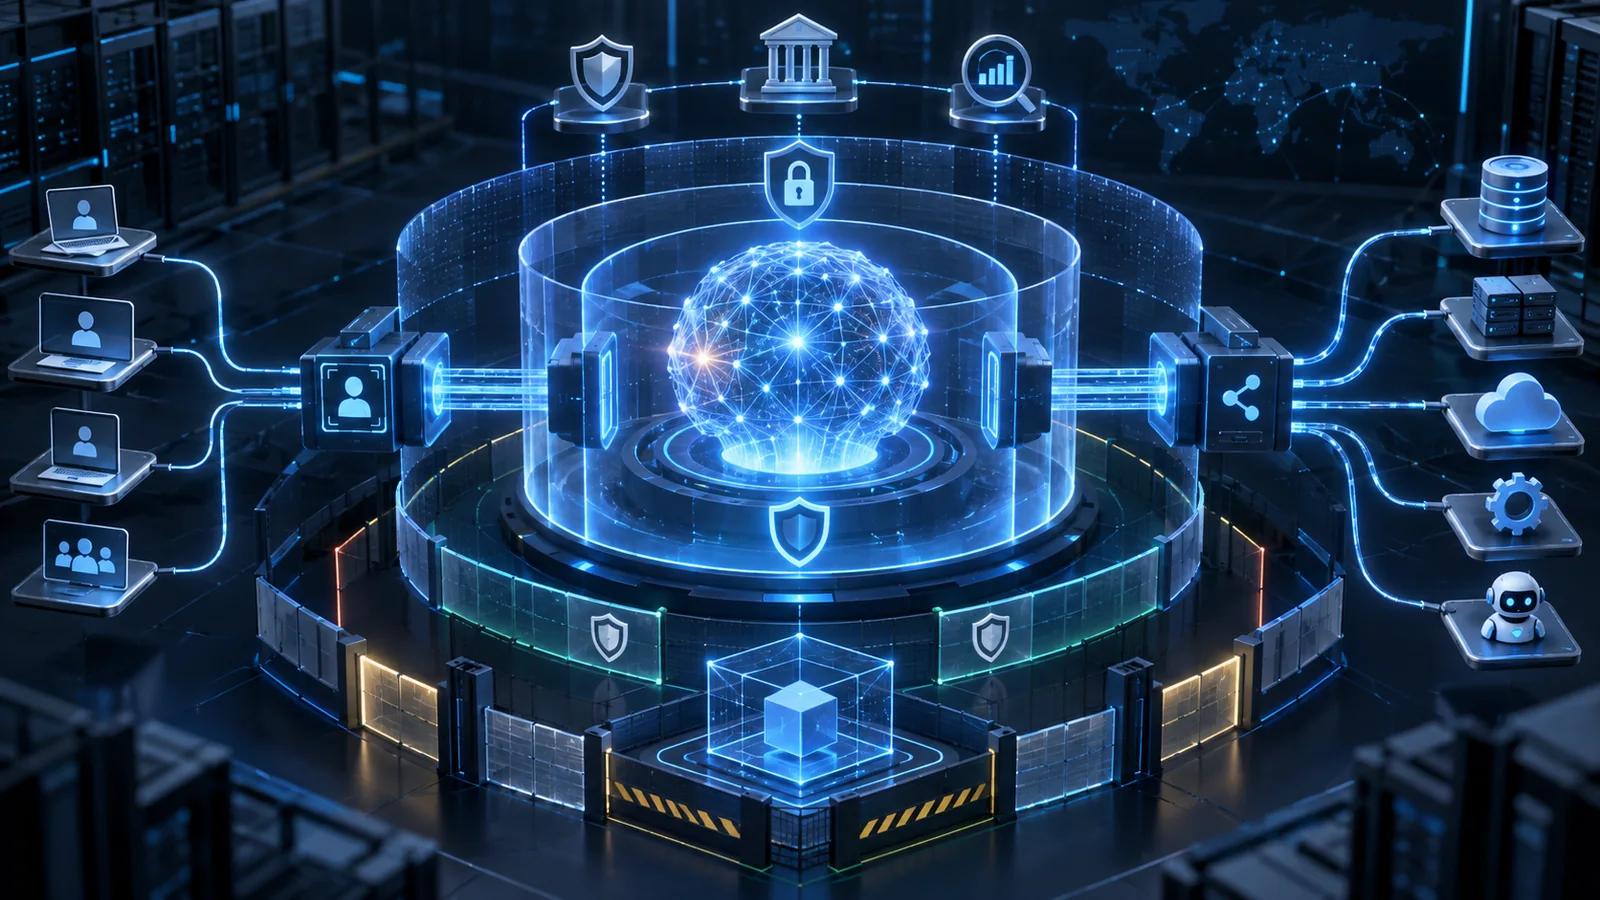
Enterprise AI is moving quickly from experimentation into production. Organisations are connecting large language models to internal documents, databases, APIs, business applications, cloud platforms and increasingly to autonomous agents that can take action.
That creates value, but it also creates a new architectural problem. Traditional security controls were designed around users, applications, networks and data. AI introduces another layer: systems that can interpret instructions, generate decisions, call tools, retrieve information and act with increasing autonomy.
The question is no longer simply, “Is the AI model secure?” A more useful question is: “Is the architecture around the AI designed so that failure, misuse or unexpected behaviour cannot easily become business impact?”
That is where AI security architecture begins.
Start With The Trust Model
Every AI system creates trust relationships. A user trusts the AI to answer correctly. The AI trusts the data it retrieves. The AI may trust an MCP server, API or plugin. A backend system may trust the AI agent to perform an action. The organisation may trust an external model provider to process sensitive information appropriately.
Those relationships should not remain implicit.
A practical AI security architecture should identify who is communicating with whom, what data is being exchanged, what authority each component has and where the trust boundaries exist. In a simple flow such as User → AI Gateway → Model → MCP Server → Enterprise Application, every arrow represents a trust decision.
Can the user access that model? Can the model call that MCP server? Can the MCP server access that application? Can the application return sensitive information? Can the AI use that information to perform another action?
If those questions are not answered architecturally, they will eventually be answered accidentally by implementation.
Identity Must Extend Beyond The Human User
AI security is increasingly an identity problem.
The human user may authenticate using SSO and MFA, but what identity does the AI agent use when accessing an internal system? Does it borrow the user’s identity? Does it use a shared service account? Does every agent have its own workload identity? Can the organisation distinguish one AI agent from another?
A shared credential may be convenient, but it weakens accountability. Enterprise AI should increasingly use identifiable, scoped and short-lived machine identities so that every agent, workload or tool invocation has permissions appropriate to the task.
An AI assistant that reads policy documents does not need write access. An agent that creates service tickets does not automatically need permission to approve them. The same least-privilege principle that applies to humans must also apply to AI.
Separate Data Access From Model Access
One of the most common AI architecture mistakes is assuming that because a user can access an AI service, the AI should automatically be able to access everything the user can access.
Those are different trust decisions.
The model may need access to internal information through retrieval, but that access should be mediated. Data classification should still apply. Confidential information should not move to an external model simply because the model provides better answers.
Sensitive datasets may require approved models, private endpoints, masking, tokenisation or local processing. The architecture should therefore answer what data can leave the organisation, what data can enter the model context, what information can be retained, whether prompts or responses can be used by the provider and whether one user can indirectly retrieve information belonging to another.
AI introduces new interfaces. It does not remove existing data-governance obligations.
Put A Control Point Between The User And The Model
As enterprise AI grows, direct connections from every application to every model become difficult to govern.
One application connects directly to one LLM provider. Another uses a different provider. A third connects to several MCP servers. Each application implements its own credentials, logging, security rules and cost controls.
That creates fragmentation.
This is why an AI Gateway can become an important architectural control point. The gateway can enforce approved models, identity policies, prompt inspection, data-loss controls, model routing, token limits, logging and MCP access.
It can also help manage cost.
A simple request should not trigger an expensive model or multiple MCP calls when a smaller model, cached response or internal knowledge source can answer the question. Security and cost management increasingly intersect here because the gateway can decide both what is allowed and what is necessary.
Treat Tools As Privileged Capabilities
AI becomes significantly more powerful when it can use tools.
A model that generates text is one risk. A model that can query databases, send emails, modify code, execute commands or trigger financial workflows is another.
MCP and similar integration patterns make those connections easier, but that convenience must not become unrestricted authority.
Each tool should be treated as a privileged capability. The architecture should define which agents can call which tools, which actions are read-only, which actions can modify data and which actions require human approval.
Tool access should be explicit, not broadly granted and not based only on what the model decides it needs.
Guardrails Are Useful. Boundaries Are Stronger.
AI safety discussions often focus on guardrails: do not reveal confidential information, do not execute harmful commands, do not perform actions outside scope.
Those instructions are useful, but instructions influence behaviour. Architecture constrains capability.
If an AI agent must never access production, production should be unreachable. If an AI agent should only read data, its identity should not have write permissions. If a testing agent should only operate inside a sandbox, unrestricted internet access should not exist.
Good AI architecture should assume the model may misunderstand, hallucinate or behave unexpectedly. The architecture should still keep the consequences limited.
A Practical Starting Framework
At a minimum, an enterprise AI architecture should answer six questions.
Who or what is making the request? Which models, tools and data sources are approved? What information can enter and leave the AI environment? What is the AI permitted to read, modify or execute? What happens when the AI attempts something outside its authorised scope? And can the organisation reconstruct what happened afterwards?
These questions provide a useful starting point before discussing products.
AI security architecture should not begin with, “Which AI security tool should we buy?”
It should begin with:
“What trust model are we trying to enforce?”
Final Thoughts
AI is becoming another enterprise computing layer, and like every other computing layer before it, security will eventually depend less on the intelligence of the technology and more on the architecture surrounding it.
Models will change. Providers will change. Agents will become more autonomous. MCP servers and tools will multiply. The architecture therefore needs principles that survive those changes.
Start with identity. Make trust explicit. Control data movement. Limit tool authority. Enforce boundaries outside the model and assume that eventually the AI will do something you did not expect.
In Part 2, the framework moves from design principles into security controls, monitoring, resilience, lifecycle management and operational governance.
Question assumptions. Share knowledge. Build trust.
Share this article
If this perspective was useful, share it with your network.