Every Trust Relationship Is An Attack Path
Security architecture must read every connection as a trust decision: who trusts whom, why the relationship exists, how much authority it grants, how long it lasts and what happens when that trust is abused.
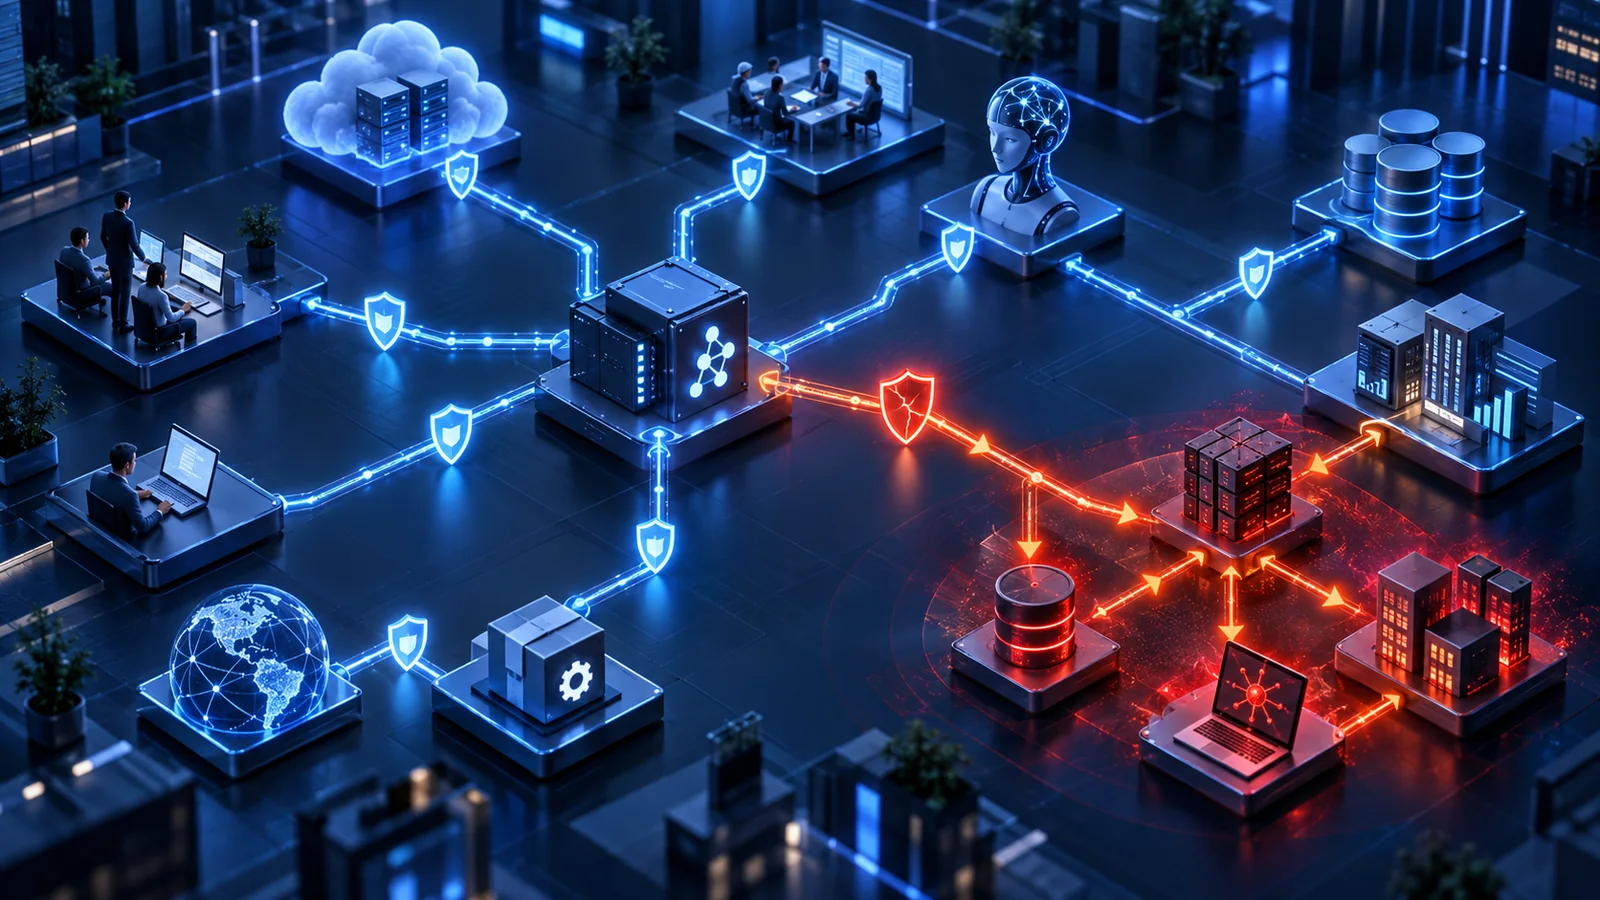
Architecture diagrams are full of arrows.
An application connects to a database. A user authenticates to a cloud service. An API calls another API. A software platform retrieves an update. An AI agent connects to an MCP server.
We normally read those arrows as connectivity.
A security architect should read them differently.
Every arrow represents trust.
System A trusts System B to accept something from it. That something may be an identity, a token, data, a command, software, or an instruction. Once that trust exists, it can potentially be abused.
The objective is not to eliminate trust. Modern technology cannot operate without it. The architectural challenge is to understand where trust exists, why it exists, how much authority it provides and what happens when that trust is wrong.
Identity Establishes Trust
Many modern trust relationships begin with identity.
A user presents credentials. A workload presents a certificate. An application uses a service identity. An API presents a token. Once the identity has been validated, another system decides what it should be allowed to do.
This is why I previously argued that The New Security Perimeter Is No Longer The Network. It Is Identity.
The network may provide connectivity, but identity increasingly determines trust.
That makes compromised identity especially dangerous. The attacker does not necessarily need to break through the system. If they can successfully inherit an existing trust relationship, the system may willingly provide access.
Machine-To-Machine Trust Is Growing Faster
The same principle applies when no human is involved.
Applications communicate through APIs. Automation platforms call cloud services. CI/CD pipelines deploy workloads. AI agents invoke tools. These interactions depend on API keys, service accounts, certificates and access tokens.
As discussed in The API Key Is Becoming The New Password, an API key is not merely configuration. It represents a machine-to-machine trust relationship.
If that credential is stolen, the attacker inherits whatever authority the receiving system associates with it.
The architectural question should therefore not only be, “Is the key encrypted?” It should also be: What can this identity access? How long does that trust remain valid? Can it be revoked? Can abnormal use be detected?
Long-lived trust creates long-lived opportunity.
Trust Should Expire When The Relationship Ends
Human identity creates another version of the same problem.
An employee leaves. The corporate account is disabled. But a personal access token continues working. A GitHub account remains authorised. An SSH key is still present. A SaaS platform was never connected to central identity governance.
I explored this in The Employee Left. The Access Did Not.
The deeper architectural problem is not merely incomplete offboarding. It is trust that survived longer than the business relationship that justified it.
Trust should have a lifecycle.
It should be established for a reason, reviewed while it remains necessary and removed when that reason disappears.
Otherwise, organisations gradually accumulate trust relationships that nobody remembers creating but attackers may eventually discover.
AI Is Creating New Trust Relationships
AI makes this problem even more interesting.
An enterprise AI system may involve a user, an AI Gateway, a model provider, several MCP servers, internal APIs, databases and business applications.
Each connection creates another trust relationship.
In The AI Gateway Should Govern Trust, Tokens And Tools, I discussed using the gateway as a control point for deciding which models, tools and MCP servers the AI should be allowed to reach.
That becomes increasingly important as AI moves from answering questions to performing actions.
An AI agent that can query HR information should not automatically be trusted to access finance. An agent that can read a repository should not automatically be able to deploy code. An MCP server trusted to retrieve information should not automatically receive authority to modify the source system.
The AI may decide which tool it wants to use.
The architecture must decide which trust relationships are permitted.
Trusted Components Can Still Become Attack Paths
One of the uncomfortable realities of cybersecurity is that trusted systems eventually fail.
A legitimate administrator account becomes compromised. A security appliance develops a vulnerability. A SaaS provider is breached. A trusted API token leaks.
This is why Good Security Architecture Assumes Every Control Will Eventually Fail remains an important architectural principle.
The important question is not simply whether a component is trusted today.
It is:
What can that trusted component reach if it becomes compromised tomorrow?
A trusted application with unrestricted database access creates one kind of blast radius. A trusted workload restricted to specific tables and operations creates another.
Good architecture does not assume trust will never fail. It limits the consequences when it does.
Even Software Trust Can Be Weaponised
Trust relationships are not limited to identities and network connections.
Software distribution is built on trust too.
Customers trust vendors. Operating systems trust certificates. Update mechanisms trust signing infrastructure. Organisations trust that software arriving through an approved channel is legitimate.
But as I discussed in The Certificate Was Valid. The Software Update Was Malicious., legitimate trust mechanisms can still distribute malicious outcomes if the attacker compromises the process before the trust decision is made.
The certificate can be valid.
The vendor can be genuine.
The update channel can be official.
And the software can still be malicious.
That is why trust must be supported by evidence, provenance and independent controls rather than a single signal.
Architecture Should Make Trust Visible
A useful security architecture review should therefore look beyond components and connectivity.
For every important relationship, ask: Who trusts whom? Why is the trust necessary? What authority is being granted? How is the relationship authenticated? How long does the trust remain valid? Can it be monitored and revoked? What happens if either side becomes compromised?
These questions often reveal risks that a normal connectivity diagram does not.
An arrow labelled HTTPS 443 tells me how two systems communicate.
It does not tell me whether they should trust each other.
That is a much more important question.
Final Thoughts
Modern enterprise architecture depends on trust.
Identity creates trust. API keys create trust. Employees accumulate trust. AI agents consume trust. Certificates establish trust. Vendors inherit trust.
The problem begins when trust becomes invisible, permanent or broader than necessary.
Security architecture should therefore treat every trust relationship as a potential attack path and design accordingly.
Make trust explicit.
Keep it minimal.
Make it verifiable.
Give it an expiry.
Monitor how it is used.
And assume that one day the thing you trust may become the thing an attacker controls.
Because every trust relationship enables the business.
And every trust relationship can also become an attack path.
Question assumptions. Share knowledge. Build trust.
Share this article
If this perspective was useful, share it with your network.