AI Security Architecture: A Practical Enterprise Framework — Part 2
AI security architecture must remain effective after deployment. Continuous observability, constrained authority, human approval, resilience testing and lifecycle governance keep changing AI systems within their intended trust boundaries.
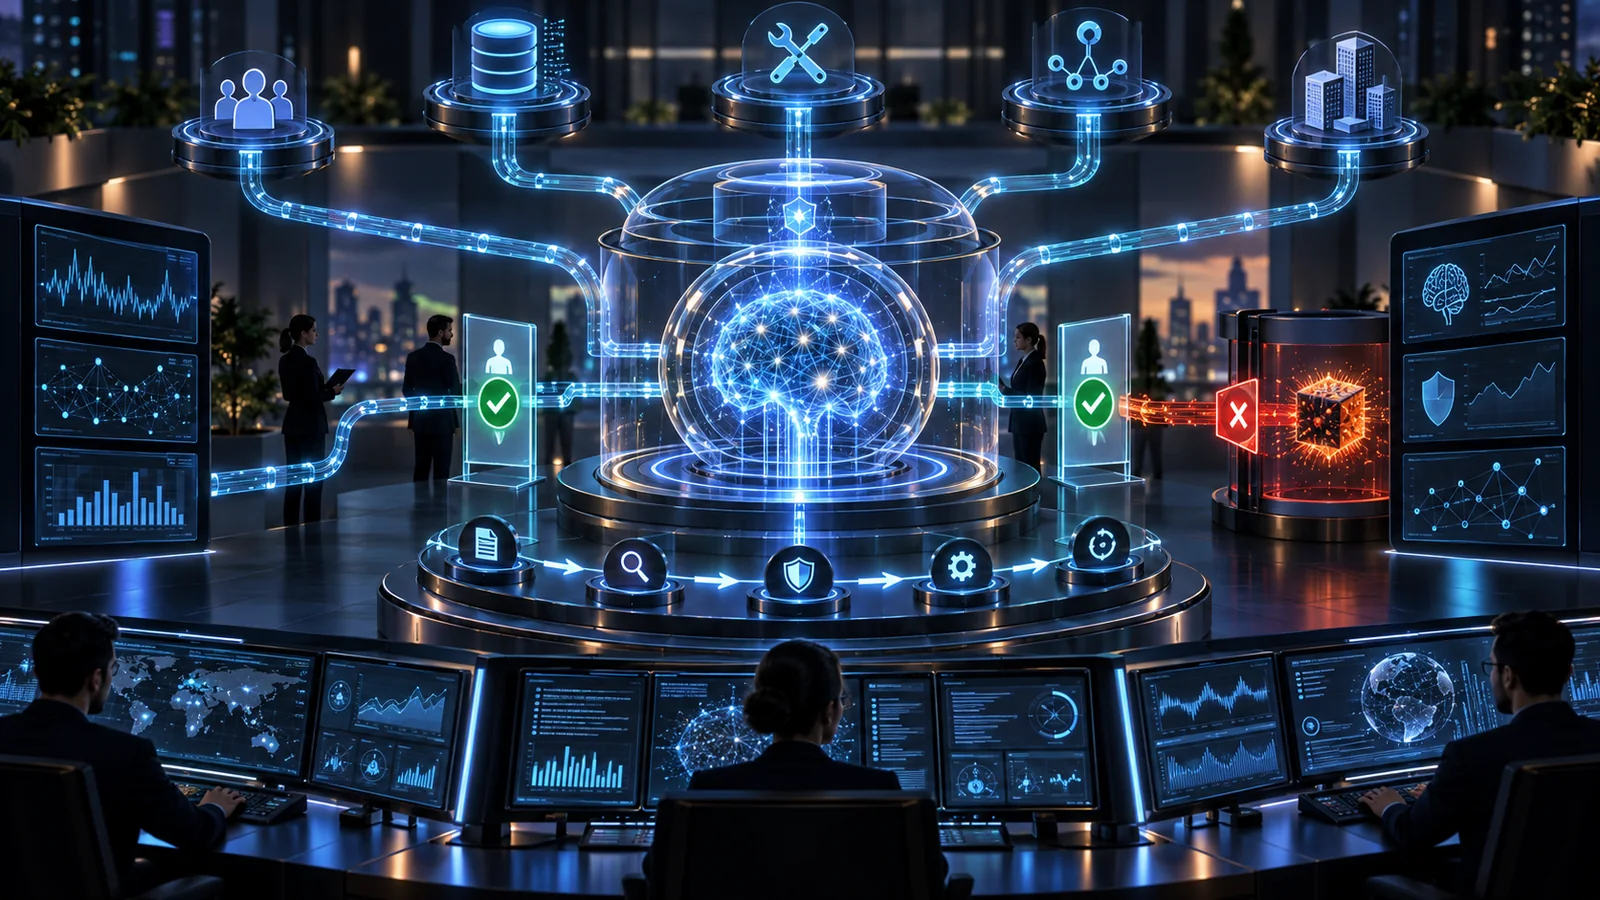
Good AI security architecture does not end when the design diagram is approved. The real test begins when the system enters production.
Models change. Agents gain new capabilities. MCP servers are added. Business teams connect new data sources. Prompts evolve. Vendors update APIs and new models appear. An architecture that was secure six months ago may no longer represent the system that exists today.
This is why AI security must be treated as an operating model, not a one-time design exercise.
Part 1 of this practical enterprise framework established the trust model, identity, data, gateway, tool and boundary principles that shape the design. Part 2 focuses on how those principles must operate in production.
Logging Must Capture More Than The Prompt
Traditional application logging may record who accessed a system and what transaction occurred. AI systems need more context.
Security teams should be able to determine who submitted the request, which model answered, which tools were called, which MCP server was used, what data was retrieved, what identity the AI used, whether the response was served from cache and whether the AI attempted an unauthorised action.
Without this information, incident investigation becomes difficult. A security team may know that an AI agent performed an action without being able to reconstruct why or how.
AI activity should therefore be observable as a chain of decisions and actions, not simply a collection of prompts and responses.
Monitor Behaviour, Not Just Availability
Traditional monitoring often asks whether a system is available.
AI monitoring needs another dimension: is the agent behaving as expected?
An AI assistant suddenly making thousands of API calls may indicate misuse. An agent that normally reads documents but begins requesting write permissions may indicate a compromised workflow. A model retrieving unusually large volumes of confidential data may represent abuse even if every individual request appears legitimate.
AI security monitoring therefore needs behavioural context. The question is not only whether the request succeeded, but whether the request should have happened at all.
Treat Prompt Injection As A Trust-Boundary Problem
Prompt injection is often discussed as though it were only a model problem.
Architecturally, it is more useful to think of it as a trust-boundary problem.
The model may receive instructions from users, documents, websites, emails or external data sources. Not all of those instructions should be trusted equally.
A document retrieved from the internet should not be able to override enterprise policy. An email should not be able to instruct an agent to transfer money. Retrieved content should therefore be treated as untrusted input.
The architecture must separate data from authority.
Just because the AI can read something does not mean the content should control what the AI is allowed to do.
Human Approval Still Matters
Not every AI action should be autonomous.
Some actions have limited impact, such as summarising a document, searching a knowledge base or drafting an email.
Others have consequences. Changing a firewall rule, creating a privileged account, approving a payment, deleting customer information or deploying code should not be treated the same way.
High-impact actions should have clear approval boundaries. Human-in-the-loop should not be treated as an inconvenience that disappears once the model becomes better. It is a control.
The more consequential the action, the stronger the independent approval should be.
Design For Model Failure
AI systems fail differently from traditional deterministic applications.
A model may produce an incorrect answer with complete confidence. It may misunderstand an instruction, choose the wrong tool, repeatedly call an API or retrieve inappropriate data.
The architecture should therefore assume model failure is normal.
Rate limits can prevent runaway activity. Tool permissions can limit impact. Transaction limits can restrict financial exposure. Network segmentation can contain movement. Approval workflows can stop high-risk actions. Fallback models can maintain availability.
The objective is not to make the model perfect.
It is to make model failure survivable.
Protect The AI Supply Chain
Enterprise AI depends on more than the model.
It depends on model providers, libraries, vector databases, embeddings, MCP servers, plugins, APIs, prompt templates and external datasets.
Each dependency introduces trust.
A compromised MCP server could manipulate what an AI agent sees. A poisoned knowledge source could influence decisions. A compromised model endpoint could expose confidential prompts. A malicious dependency could gain access to credentials.
AI security therefore becomes another software supply-chain problem.
Organisations should maintain an inventory of approved models, agents, MCP servers, tools and external AI services because you cannot govern what you do not know exists.
Build Lifecycle Governance Around AI
AI systems evolve quickly, and that creates a lifecycle problem.
Who approves a new model? Who reviews a new MCP integration? Who decides whether a model can process confidential data? Who owns the AI agent? Who removes access when the application is retired? Who reviews permissions when the agent’s purpose changes?
These are governance questions.
Every enterprise AI capability should have an owner, a defined purpose, authorised data access, approved tools and a review cycle. Temporary experiments should also have expiry dates because pilots have a habit of quietly becoming production systems.
Test The Architecture, Not Just The Model
AI security testing should go beyond asking whether the model produces harmful output.
Test the boundaries around it.
Can the agent access systems outside its authorised scope? Can it call an MCP server it should not reach? Can a malicious document manipulate tool execution? Can one user retrieve another user’s information? Can token limits be bypassed? What happens if the primary AI provider becomes unavailable? What happens if the model begins calling the same tool repeatedly?
These are architecture tests.
The objective is not merely to determine whether the model behaves safely. The objective is to determine whether the enterprise remains safe when it does not.
Final Thoughts
AI security architecture requires a different mindset.
Do not protect only the model. Protect the identities around it, the data moving through it, the tools it can reach and the actions it performs. Limit the consequences when it fails and govern the entire lifecycle.
A practical enterprise framework therefore comes down to a simple principle:
The AI should never have more trust, access or authority than the business outcome requires.
The model can be intelligent.
The architecture must still be disciplined.
Because the most important question in enterprise AI is not what the model is capable of doing.
It is what the organisation has allowed it to do.
Question assumptions. Share knowledge. Build trust.
Share this article
If this perspective was useful, share it with your network.