Every AI Use Case Should Have an Owner, a Boundary and a Kill Switch
As enterprise AI gains access to data, tools and business systems, every use case needs more than a sponsor: it needs an accountable owner, enforceable boundaries and an independent way to stop it.
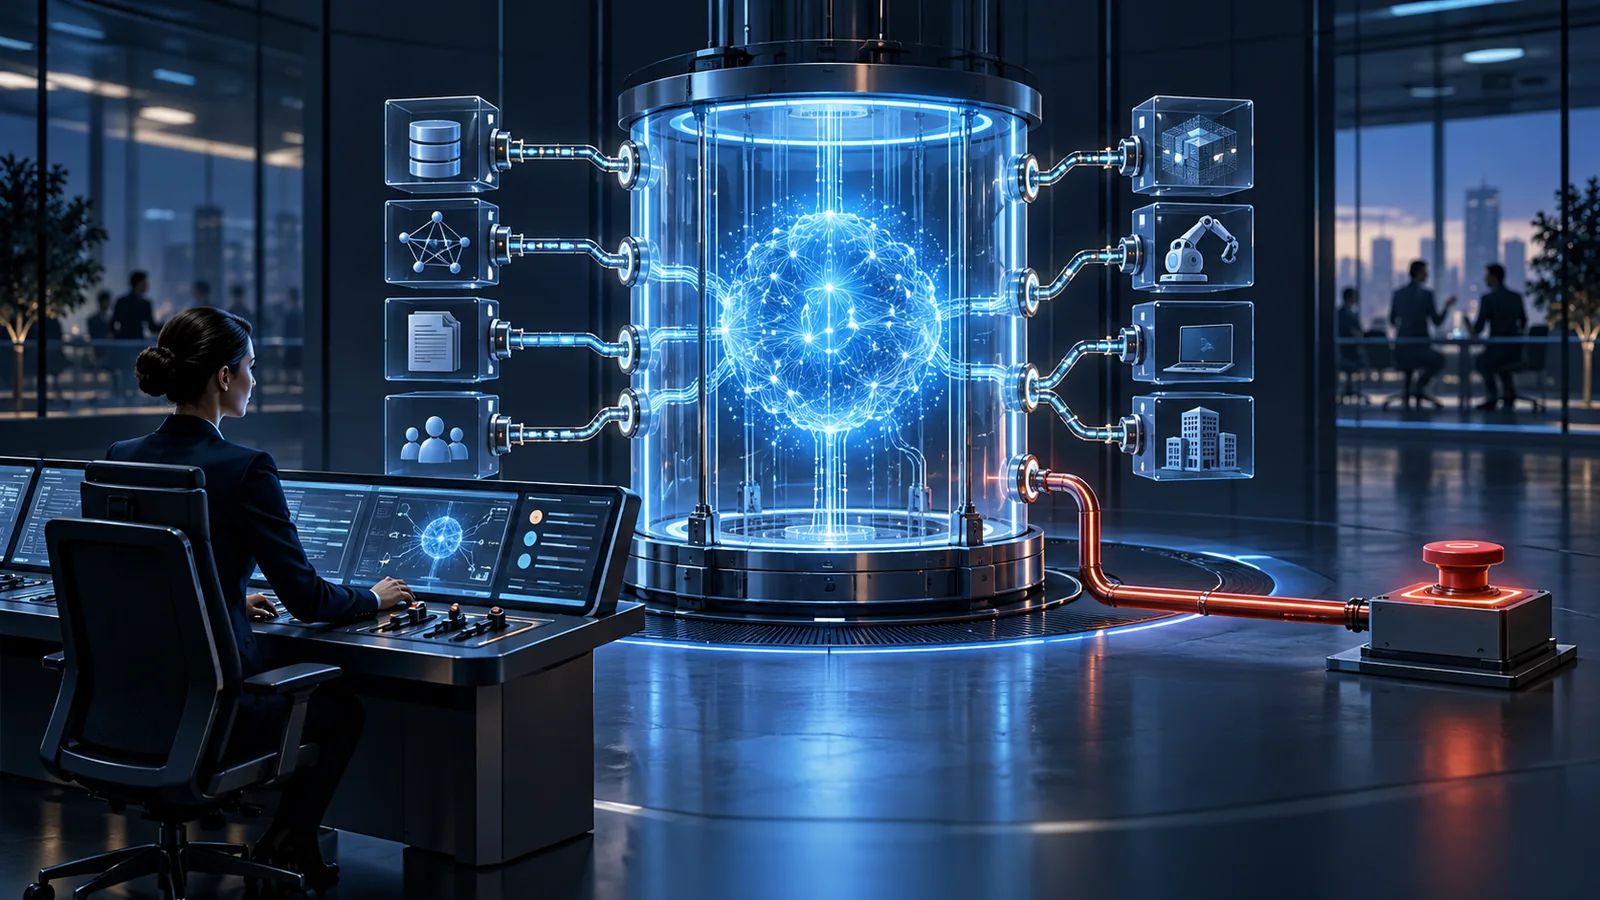
Enterprise AI adoption is accelerating faster than most governance models were designed to handle.
A business team experiments with a chatbot. A developer connects an LLM to an internal API. An operations team introduces an AI assistant. Another team adds an MCP server so an agent can reach business systems.
Individually, each use case may look small.
Collectively, they create a new operating environment where AI can read data, call tools, make decisions and increasingly take action.
That means every AI use case needs more than a business sponsor.
It needs an owner, a boundary and a kill switch.
The Owner Answers For The Use Case
Every AI capability should have a clearly identified owner.
Not just the team that built it.
Not just the vendor that provides the model.
The owner should be accountable for why the AI exists, what business outcome it supports, what data it uses, what systems it can reach and what level of risk the organisation is willing to accept.
This becomes especially important when an AI proof of concept quietly becomes part of day-to-day operations.
Pilots often start with limited access and few users. Over time, more data sources are connected, more permissions are granted and more teams begin to depend on the capability.
Without a named owner, that growth can become unmanaged.
Ownership is what keeps the use case tied to a business purpose rather than allowing capability to expand simply because the technology makes it possible.
The Boundary Defines What The AI Is Allowed To Do
Ownership alone is not enough.
The architecture still needs to define boundaries.
What data can the AI access? Which models can it use? Which MCP servers can it call? What tools can it invoke? Can it read only, or can it modify data? Can it reach production? Can it send information outside the organisation?
These are architectural questions.
In AI Security Architecture: A Practical Enterprise Framework, I argued that AI security should begin with the trust model, not with the product. The organisation needs to understand who or what is making the request, which tools and data sources are trusted, and where the boundaries actually exist.
The same principle applies to every individual AI use case.
An AI assistant that summarises internal policy documents should not inherit the same access as an agent that operates business workflows.
A coding assistant should not automatically reach production credentials.
An AI agent that creates tickets should not automatically have permission to approve or close them.
The boundary should reflect the business outcome.
Not the maximum capability of the technology.
A Boundary Must Be Technically Enforced
Policies are useful.
Instructions are useful.
Prompt guardrails are useful.
But none of them should be confused with a security boundary.
If an AI use case is not allowed to access production, then production should be technically unreachable. If the agent should only read data, the identity it uses should not have write privileges. If an MCP server is not approved for a particular use case, the agent should not be able to call it.
This is the same distinction discussed in AI Agents Need Security Boundaries, Not Just Safety Guardrails.
A guardrail tries to influence behaviour.
A boundary limits capability.
For enterprise AI, both matter. But when the model behaves unexpectedly, the boundary is what determines the consequence.
The Kill Switch Is The Control Nobody Wants To Need
The third requirement is the one organisations often forget.
How do you stop the AI?
Not eventually.
Immediately.
Imagine an AI agent begins making repeated transactions. A model starts returning inappropriate information. An MCP server is discovered to be compromised. A vendor reports a security incident. The AI begins calling tools outside its normal pattern.
Can the organisation disable the use case quickly?
A kill switch should not depend on the AI deciding to stop itself.
The organisation should be able to revoke the agent identity, disable tool access, disconnect the MCP integration, block model access or stop outbound connectivity independently of the model.
This principle also connects to If Your AI Test Can Reach The Real Internet, It Is Not Really A Sandbox. Containment should be enforced outside the AI, because the system being controlled should not be the only system responsible for controlling itself.
The Kill Switch Must Match The Blast Radius
Not every AI use case requires the same emergency controls.
A chatbot that answers questions from public information creates a different risk from an autonomous agent with access to financial systems.
The more authority the AI has, the stronger the isolation and shutdown mechanisms should be.
This links directly to The Strongest Architecture Is The One That Limits Blast Radius.
If one AI use case becomes compromised, how much of the organisation can it affect?
If the answer is “many systems, many users and many data sources,” the architecture has concentrated too much authority.
The kill switch is useful.
A smaller blast radius is better.
AI Gateways Can Help Enforce The Model
For organisations running multiple AI use cases, central control becomes important.
An AI Gateway can help enforce approved models, identity policies, token limits, data controls, logging and MCP access. As discussed in The AI Gateway Should Govern Trust, Tokens And Tools, the gateway can become a control point for both security and cost.
It can also become part of the kill-switch design.
If an AI use case needs to be suspended, the gateway may be able to block the model, revoke routing, prevent MCP calls or restrict the agent to a safer mode.
That is much easier than trying to locate dozens of direct model integrations during an incident.
Central control does create concentration risk, so the gateway itself must be resilient and strongly governed.
But without some form of coordinated control plane, enterprise AI can quickly become fragmented.
The Lifecycle Matters Too
Owner, boundary and kill switch should not be defined only at launch.
AI use cases change.
New data sources are connected. New tools are added. The model changes. A read-only assistant becomes an autonomous workflow. A temporary pilot becomes permanent.
The original risk assessment may no longer describe the system.
Every AI use case should therefore have a review cycle.
Is the owner still valid? Is the business purpose unchanged? Are the permissions still appropriate? Are all connected tools still required? Has the blast radius increased? Does the kill switch still work?
AI governance should not assume that approval is permanent.
Trust should evolve with the use case.
Final Thoughts
Enterprise AI does not need to be slowed down by excessive governance.
But it does need accountability and control.
Every use case should have someone who owns the outcome.
Every use case should have boundaries that limit what the AI can see and do.
Every use case should have a way to stop it when the assumptions behind the design are no longer valid.
These are simple principles, but they create a useful test for any AI proposal.
Who owns it?
Where does it stop?
How do we stop it?
If those three questions cannot be answered clearly, the use case is probably not ready for production.
Because responsible AI adoption is not only about allowing AI to work.
It is also about making sure the organisation remains in control when it does not.
Every AI use case should have an owner, a boundary and a kill switch.
Question assumptions. Share knowledge. Build trust.
Share this article
If this perspective was useful, share it with your network.